
Data Engineering
Snowflake Cost Optimization That Starts With a Real Audit
A lower Snowflake bill matters only if essential dashboards, pipelines, and operational requests still work. First identify which cost category...
Planning a new data platform? Start with what you already have: GroupBWT goes through your sources, reports, and cloud accounts first. The recommendation comes after that. As a data lake consulting company, we’ll tell you if a lake, a warehouse, or a lakehouse fits, and write the roadmap your engineers or ours will build from.





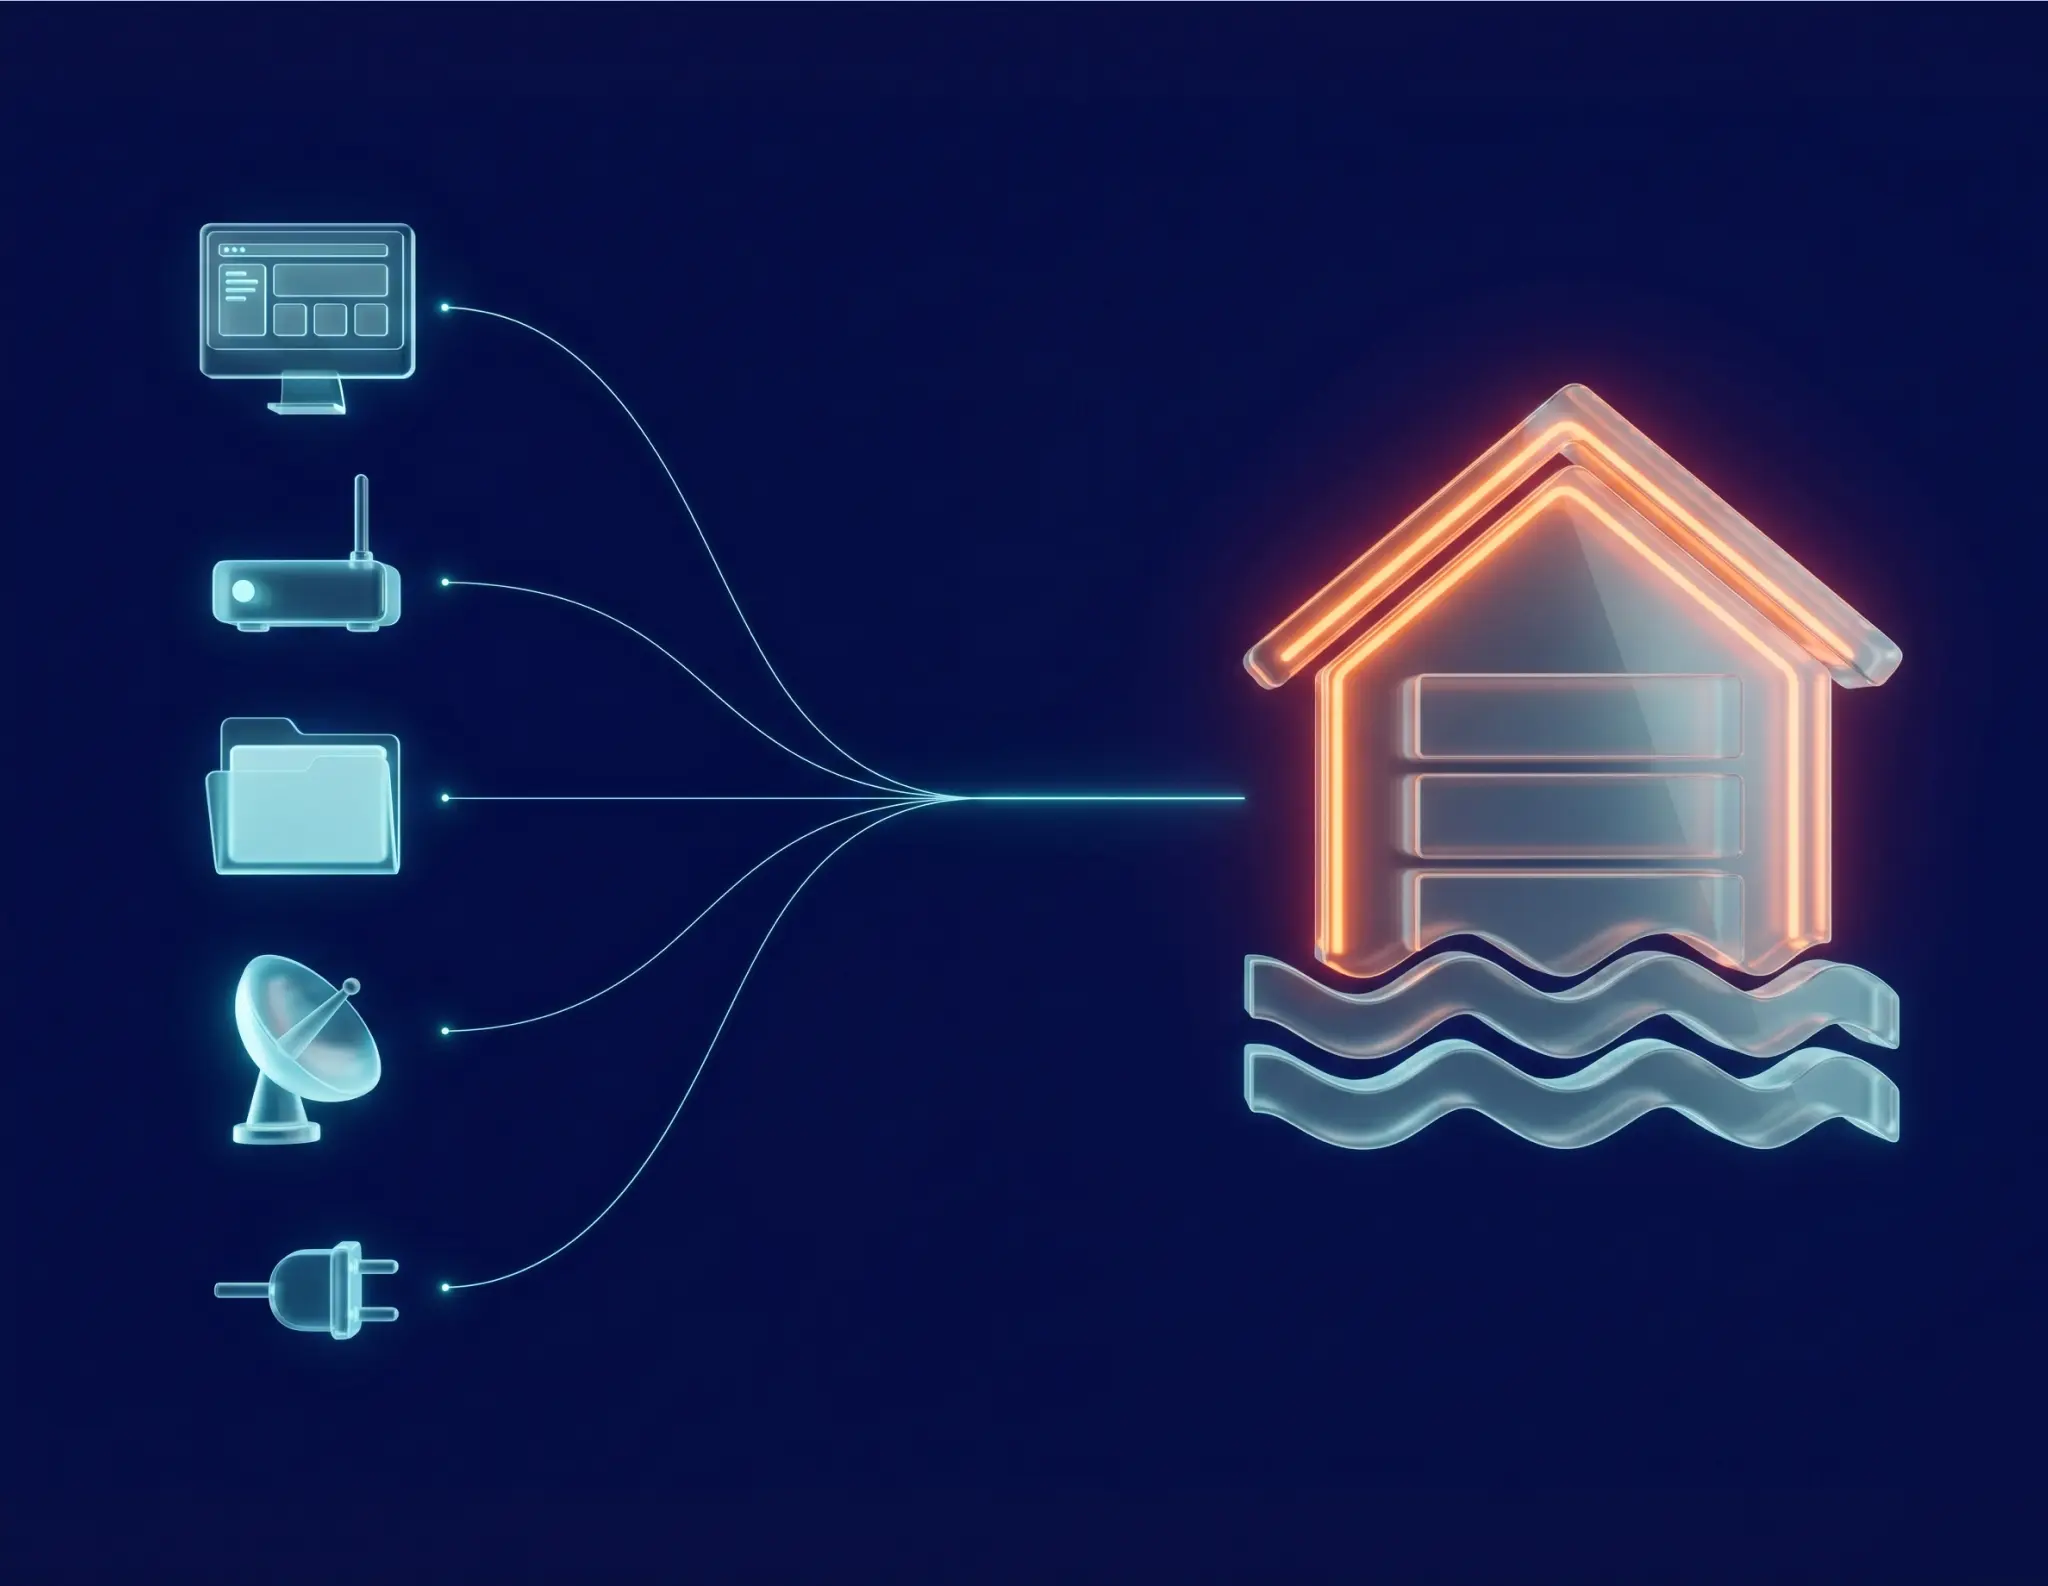
More tools, databases, and apps mean more data. On its own, that’s not a problem. It becomes one when files have no owner and reports run on logic nobody can trace.
Siloed Data Sources
The same figure lives in several department files, each one calculated with slightly different definitions. Reports wait while an analyst reconciles those files by hand, often for several hours. We map every source and owner, then design one landing zone with shared definitions.
Delayed Reporting
Each reporting cycle opens with manual cleanup, so numbers reach managers after the decision is made. We move validation and business logic upstream, and dashboards then read prepared tables.
Unstructured Storage
Files land in object storage without a description, and nothing stops them. Months later someone goes looking for one of them, and there's no metadata to search and no owner to ask. There's no retention rule on it either, so it stays put, since nobody wants to delete something they can't identify. That's how a lake turns into a data swamp. Our answer is storage zones, catalog rules, and naming standards, so the next person looking for a dataset actually finds it.
Unpredictable Cloud Costs
The invoice keeps growing, and nobody can point to the workload responsible. We go through the invoice and tie each cost to the workload behind it. Then anything that's read only now and then can move to a cheaper storage tier, with fewer refreshes.
The best route depends on what is broken now. Many enterprises need two or three of these paths at once, and our data lake consulting solutions combine them into one plan.



Perhaps there’s a vendor proposal in your inbox, or a design your own architects sketched. Send it over. On a free fit call, GroupBWT shows where it may cost more than planned or break the reports you already run.
No model wins everywhere. Your data, the jobs on top of it, and the governance rules you answer to should decide it. Every row includes a typical enterprise example:
Best Fit and Example:
Governance & Cost Factors:
Years of raw history kept at low cost for later analysis. Example: an insurer keeps claim documents for future fraud models.
Each raw dataset needs an owner and a retention period. Spend follows retained volume and read frequency.
Curated models that many report users query at once. Example: store managers at a retailer check yesterday's sales on one shared dashboard.
Access opens once the schema and permissions are approved. Compute, concurrency, and refresh frequency set the spend.
Shared tables for BI and machine learning on one storage layer, plus a warehouse only where reports need it. Example: a manufacturer's data scientists train a maintenance model without copying the sensor tables its plant dashboards use.
Transactions and version history need Apache Iceberg or Delta Lake plus a configured table catalog. Spend follows storage tiers, table maintenance, and compute.
Data Lake
Best Fit and Example
Governance & Cost Factors
Data Warehouse
Best Fit and Example
Governance & Cost Factors
Lakehouse or Hybrid
Best Fit and Example
Governance & Cost Factors
You keep five documents from our big data lakes solutions and consulting services. Leadership approves them and finance budgets against them. Engineers then build from the same set. So the cost model is written for finance, and the blueprint and handoff package are written for engineers.
Diagrams and specs trace the path from each source through storage and processing to the reports. Your architects sign it off together with security and engineering, before any code exists.
Every dataset in scope gets an entry. The entry lists the owner and everyone with access, then the quality checks the data must pass and how long it is kept. Security and compliance teams get review evidence before any data moves.
Expected usage comes first, workload by workload. Storage, compute, and refresh costs are worked out from there. Finance gets a defensible spending range and sees which design choices move the bill.
Sources and dependencies are ordered into phases, each with a validation point. Reports keep running on the old platform until each phase is checked.
Transformation standards, runbooks, and decision records are written so your engineers, a contractor, or GroupBWT can execute them. You own every artifact.
First question we ask: what decision does this platform have to support? Often it’s something like a faster month-end close. A layer that no named report, model, or team needs stays out of the design. So does storage nobody will read.
A US agricultural producer was leaving a SQL Server warehouse it had relied on for 12 years. GroupBWT audited 260+ Power BI artifacts and confirmed that 155 of them belonged in scope. That map let GroupBWT plan parallel migration streams with no full cutover.
GroupBWT can carry the design into production. For a global cosmetics manufacturer, a six-week pilot of three retailer pipelines grew into a GroupBWT team that has put 40+ pipelines from 24+ countries into production.
GroupBWT built a platform for a US investment firm in which data passes through raw, validated, and reporting layers. The quality jobs sit in the validated layer, and records that fail them are held there instead of flowing into reports. GroupBWT also made every figure traceable to its source.
We’ve put production pipelines on Azure and built a governed Databricks platform. AWS, Google Cloud, and Snowflake are also options we plan for, working from the cloud contracts you hold and the tools your team runs.
Each source gets one spec. It covers format, refresh frequency, and owner, plus every report that would break if the source changed. Engineers can estimate and code from it without another round of business interviews.
On the same agricultural migration, GroupBWT documented every source in a system design document before migration code was written. When the client added a financial ERP midway, GroupBWT folded it into the 18-source, three-phase plan.
GroupBWT pulled 40+ KPI definitions out of the investment firm’s Power BI formulas and into a governed layer, documenting and versioning each one. That lets the firm switch BI tools without rebuilding them.
What Our Clients Say

What do you like best?
Their deep understanding of our needs and how to craft a solution that provides more opportunities for managing our data. Their data solution, enhanced with AI features, allows us to easily manage diverse data sources and quickly get actionable insights from data.
What do you dislike?
It took some time to align the a multi-source data scraping platform functionality with our specific workflows. But we quickly adapted and the final result fully met our requirements.

What do you like best?
It was incredible how they could build precisely what we wanted. They were genuine experts in data scraping; project management was also great, and each phase of the project was on time, with quick feedback.
What do you dislike?
We have no comments on the work performed.

What do you like best?
GroupBWT is the preferred choice for competitive intelligence through complex data extraction. Their approach, technical skills, and customization options make them valuable partners. Nevertheless, be prepared to invest time in initial solution development.
What do you dislike?
GroupBWT provided us with a solution to collect real-time data on competitor micro-mobility services so we could monitor vehicle availability and locations. This data has given us a clear view of the market in specific areas, allowing us to refine our operational strategy and stay competitive.

What do you like best?
The company's dedication to understanding our needs for collecting competitor data was exemplary. Their methodology for extracting complex data sets was methodical and precise. What impressed me most was their adaptability and collaboration with our team, ensuring the data was relevant and actionable for our market analysis.
What do you dislike?
Finding a downside is challenging, as they consistently met our expectations and provided timely updates. If anything, I would have appreciated an even more detailed roadmap at the project's outset. However, this didn't hamper our overall experience.

What do you like best?
GroupBWT excels at providing tailored data scraping solutions perfectly suited to our specific needs for competitor analysis and market research.
What do you dislike?
Given the complexity and customization of our project, we later decided that we needed a few additional sources after the project had started.
What do you like best?
What we liked most was how GroupBWT created a flexible system that efficiently handles large amounts of data. Their innovative technology and expertise helped us quickly understand market trends and make smarter decisions.
What do you dislike?
The entire process was easy and fast, so there were no downsides.
What do you like best?
Their deep understanding of our needs and how to craft a solution that provides more opportunities for managing our data. Their data solution, enhanced with AI features, allows us to easily manage diverse data sources and quickly get actionable insights from data.
What do you dislike?
It took some time to align the a multi-source data scraping platform functionality with our specific workflows. But we quickly adapted and the final result fully met our requirements.
What do you like best?
It was incredible how they could build precisely what we wanted. They were genuine experts in data scraping; project management was also great, and each phase of the project was on time, with quick feedback.
What do you dislike?
We have no comments on the work performed.
What do you like best?
GroupBWT is the preferred choice for competitive intelligence through complex data extraction. Their approach, technical skills, and customization options make them valuable partners. Nevertheless, be prepared to invest time in initial solution development.
What do you dislike?
GroupBWT provided us with a solution to collect real-time data on competitor micro-mobility services so we could monitor vehicle availability and locations. This data has given us a clear view of the market in specific areas, allowing us to refine our operational strategy and stay competitive.
What do you like best?
The company's dedication to understanding our needs for collecting competitor data was exemplary. Their methodology for extracting complex data sets was methodical and precise. What impressed me most was their adaptability and collaboration with our team, ensuring the data was relevant and actionable for our market analysis.
What do you dislike?
Finding a downside is challenging, as they consistently met our expectations and provided timely updates. If anything, I would have appreciated an even more detailed roadmap at the project's outset. However, this didn't hamper our overall experience.
What do you like best?
GroupBWT excels at providing tailored data scraping solutions perfectly suited to our specific needs for competitor analysis and market research.
What do you dislike?
Given the complexity and customization of our project, we later decided that we needed a few additional sources after the project had started.
What do you like best?
What we liked most was how GroupBWT created a flexible system that efficiently handles large amounts of data. Their innovative technology and expertise helped us quickly understand market trends and make smarter decisions.
What do you dislike?
The entire process was easy and fast, so there were no downsides.
When you outsource big data lakes solutions and consulting services to GroupBWT, the work runs in four stages, starting with your current estate and ending with a build plan you can fund.
What should we prepare before we start?
Not much. Three things are enough to begin:
Two more questions from our side: who owns each source, and do HIPAA, GDPR, or similar rules apply? Missing pieces are fine. We sort those out in the first stage.
Do we need a lake, a warehouse, or a lakehouse?
First we look at what formats your data comes in and how fresh it has to be. Then come concurrent users and budget. Whichever setup handles all four is the one we recommend. Quite often it’s a mix, like a lake for raw history plus a warehouse for finance reporting. We write down every trade-off so your team can push back on it.
Can you review a data lake or design we already have?
Yes. We review both live lakes and designs your own team has drawn up, looking at performance, security, scaling limits, and cost. When the lake is already running, we usually start by looking for tables nobody owns. Then we find the queries behind most of the bill and the pipelines that fail without alerting anyone. From there, it’s your call. Our engineers can join your team to fix the issues, or your team can work through the prioritized plan alone.
How much time do data lake consulting services need?
Source count matters most. Next come the hidden dependencies between sources, and the level of governance and documentation you need. In practice, untangling business logic from stored procedures or spreadsheets is what takes longest. After the fit call you get a range. After the assessment, a firm estimate. Should the scope change later, we send a revised estimate and explain what drove it.
What exactly do we get when the engagement ends?
The handover is a single versioned package, committed to your repository or saved in your document space. You can edit every diagram, spec, and cost model in it directly. When the platform changes, your team updates them. We also run working sessions where your team goes through the package with us and challenges any assumption it doesn’t buy.

How can we help you?
We’ll review your goals and suggest the right solution — technical, scalable, and tailored to you.
What do you need extracted, structured, or automated?