ETL Development
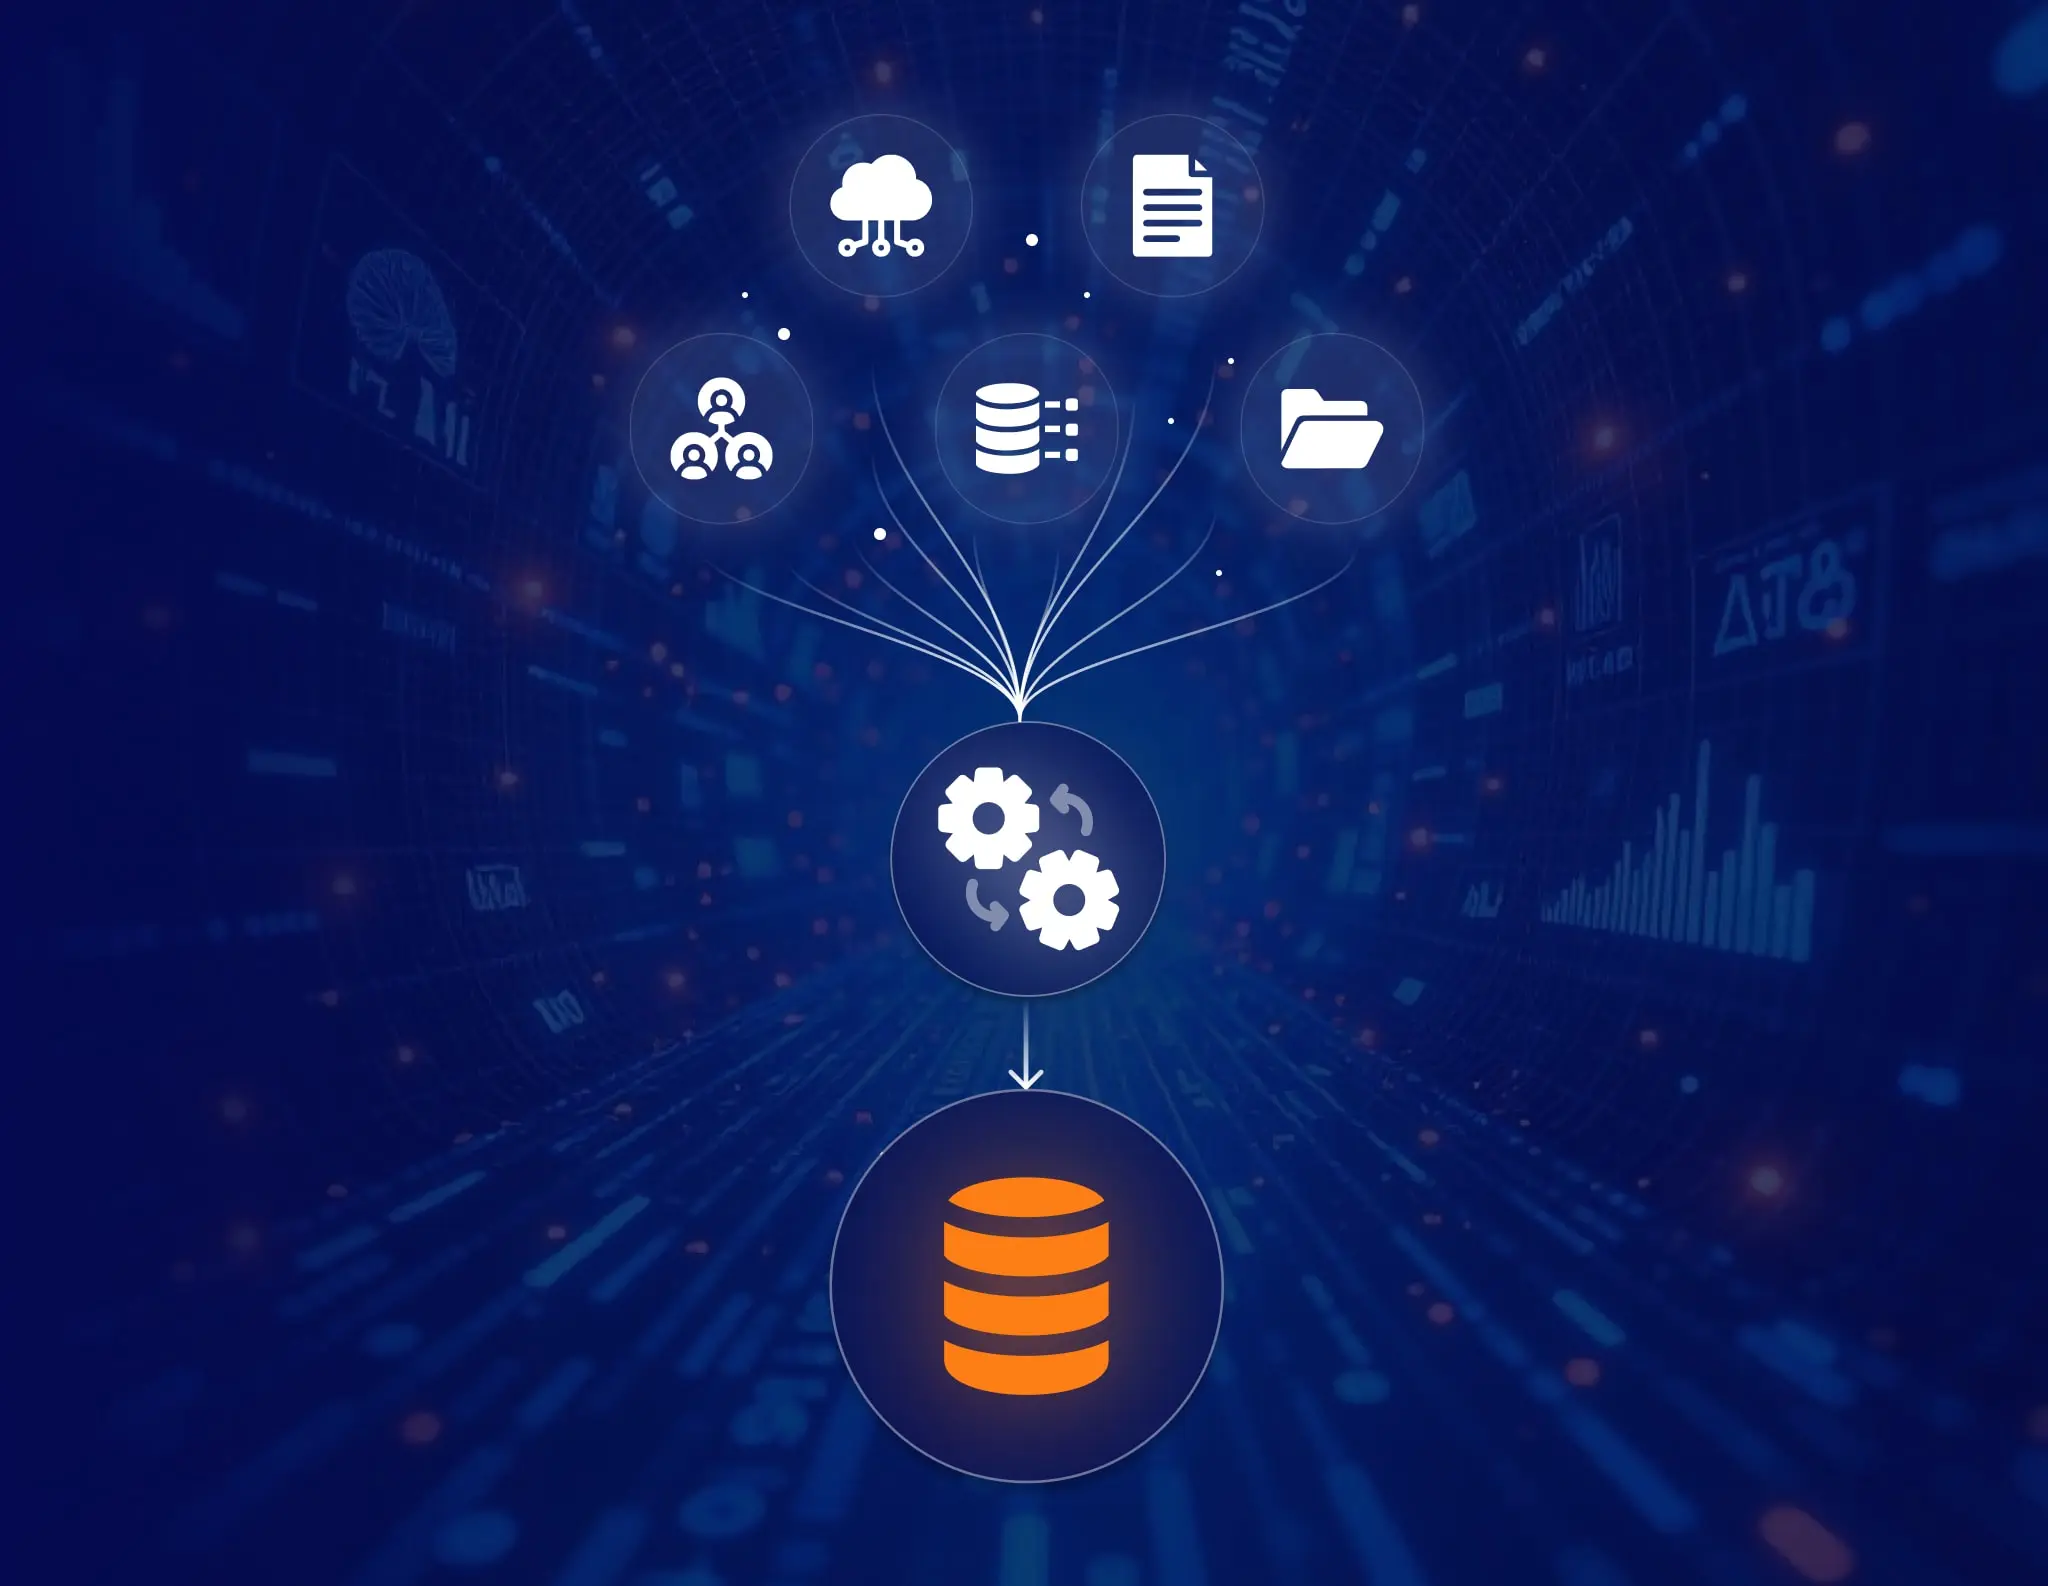
GroupBWT designs and builds reliable data flows for your new platforms or reporting tools. Approved records reach the analytics dashboard through a flow that cleans the source data.
GroupBWT designs, builds, and supports ETL (extract, transform, load) pipelines: scheduled jobs that carry business-system data into the reports your leaders read. For fast-growing companies, we catch a late or conflicting report before an executive does and keep the processing bill predictable. New pipelines, platform moves, and fixes to existing data flows all sit within our ETL consulting services.
Select the service route that addresses your current operational challenge.
GroupBWT designs and builds reliable data flows for your new platforms or reporting tools. Approved records reach the analytics dashboard through a flow that cleans the source data.
GroupBWT moves your data pipelines to new storage systems or cloud platforms. We check the agreed metrics against historical baselines before the production release.
We establish whether the platform is responsible before recommending that you change it. Often the stack can stay. The fix sits in the slow run, hidden failure, or missing operating control.
Scope one area or several. Where we begin depends on which report or system breaks first.
The central warehouse is the base; every department reads from a mart built on top. We give every mart agreed metric definitions, naming rules, and a refresh schedule. The sales dashboard and the finance report then agree on revenue for March, or any other period.
Sources come in four kinds: databases, SaaS applications, partner files, and public web sources. We connect all four. Large tables move to incremental loads. Source health checks look for a broken connector or a renamed field. The analyst sees that alert before the change reaches a report.
We drop duplicate rows. A customer or product listed twice under different records? They become one record. Amounts go to one currency; units and time zones get the same treatment. Every rule comes with a short note, in plain English, on what it does. A finance lead can check the logic from it without reading SQL.
Process design decides where each transformation runs. Some rules must run before loading. Others run later, inside the warehouse, once the data has landed – that’s ELT (extract, load, transform). Our ELT consulting services handle that warehouse side too, plus run schedules, job dependencies, and backfills that reload past periods.
Do the target’s rows and totals match the source? We check automatically, after every load. A release ships only after regression tests show that accepted figures did not move. A failed check stops the load and holds the suspect figure for review.
Is a forecast or machine learning model next? We build the model-ready tables it needs. Their definitions are locked, and each refresh runs the same way. We also watch input data for shifts. The data science team then trains on figures that reporting already trusts.
Scope sets the package. Each item below helps your team run or review its data flows.
The return shows up in how your teams use the numbers every week.
The amount of data is rarely the hard part. Runs that break are. As an engineering partner, GroupBWT builds secure pipelines with monitoring built in. Silent errors surface, and capacity grows as your business does.
Source systems and reporting rules differ by sector. Each card names a typical first job.
Finance
At banks and FinTech platforms, an audit trail rides with each ledger entry, payment event, and risk feed we load. Month-end close and the regulatory reports both work from the same validated transactions.
Insurance
Insurers’ policy, claims, and broker data tend to sit in older core systems. We bring it together, and loss ratios and claim cycle times get one definition.
Healthcare
We mask or tokenize patient-related records before anything reaches analytics storage. Who may see which dataset is written down, reviewer by reviewer.
E-Commerce
One model holds orders, returns, marketplace feeds, and ad spend. Margin by product and channel gets calculated there once and shared.
Retail
Store A’s point-of-sale file rarely matches store B’s. Inventory and supplier files differ too. We standardize it all, and merchandising sees stock and sell-through without juggling files.
Telecommunications
We roll up usage records and billing events, which grow fast, in scheduled windows. Churn and network reports stay current without overloading source systems.
Manufacturing
Plants often run different systems. We map their production, quality, and ERP data to shared product and site codes. Then one report can compare them.
Beauty & Personal Care
Product names in retailer sell-out files seldom match those in marketplace reviews or marketing platform data. We normalize them to one catalog for brand and assortment reporting.
Travel and Hospitality
Booking, rate, and channel data reload daily. Revenue teams no longer paste exports together to compare occupancy and channel performance.
Micromobility
How busy is each zone of a shared fleet? Trip, telemetry, and maintenance data answer that in our utilization reports. Transportation and logistics teams ask a different question: which deliveries ran late? Shipment, carrier, and transit-time data feed the on-time delivery report we build for them.
Every project runs from a look at today’s setup to an agreed production release and handover.
01
Audit Reports and Sources
Name your team’s most frustrating report. We start with that report, then trace its source systems, connections, and access limits in turn. The review shows where data breaks and which fix should come first.
02
Choose Architecture and Tools
A transformation can run before the load or after it. We place each one by data volume, refresh needs, security rules, and budget. Building starts once you approve the target design, owners, acceptance checks, and tools.
03
Build Pipelines and Tests
Each short iteration builds or upgrades a few data flows, and we test every output against the approved baseline reports. Your team reviews working results early, well before the full release.
04
Deploy Pipelines and Monitoring
Release happens in stages. At each one we check live outputs against the baseline reports and show your internal team how each flow works. Support continues on the terms agreed before launch.
Azure and AWS S3
In delivered pipelines, we have stored and delivered data using Microsoft Azure and Amazon Web Services S3.
PostgreSQL, Redshift, MySQL
In delivered work, we loaded pipeline data into PostgreSQL, Amazon Redshift, and MySQL environments.
Python, SQL, Polars
We have written delivered transformations in Python, SQL, and Polars for file parsing, normalization, and processing logic.
Kubernetes, Docker, ArgoCD
Production deployments we delivered used Kubernetes, Docker, ArgoCD, Helm, and GitLab CI.
RabbitMQ, Redis, MySQL
RabbitMQ, Redis, and MySQL coordinate queued jobs and retain the state needed to follow their progress.
Grafana, Tableau, Metabase
Grafana, Tableau, and Metabase have supported teams checking pipeline health and working with the resulting data.
What Our Clients Say
An ETL consulting company should not lose the business rule between design and code. GroupBWT carries the agreed rule into implementation, acceptance, and handover.
Scope That Grows Source by Source
A first release can cover a few sources and one report. For a cosmetics manufacturer, GroupBWT started with three retailer pipelines in a six-week proof of concept and has since grown the platform to more than 40 production pipelines.
Engineers Working Inside Your Stack
If you prefer, our engineers work in your own repositories, your deployment pipeline (CI/CD), and your code review. Pipelines pass your review before release, like any in-house engineer's work, and all code stays in your environment.
Web Data and Internal Data Together
We also extract public web data, such as prices or reviews, and model it next to your internal records. For a hospitality pricing platform, we built two production pipelines that deliver daily competitor rates to an AI pricing engine.
Named Ownership After Every Release
Engagement documents name who approves metric definitions, reviews releases, and maintains each flow after launch. When people change on your side or ours, accountability for every production flow stays clear and written down.
Related Data Services
Reports need one place to read from. We build that warehouse, including its data models, access controls, and versioned business logic.
Existing data sets the design boundary. We translate your existing sources, schemas, storage needs, and access rules into requirements for the design.
We plan where a large workload will land in storage. The plan fixes the file format, partition logic, and route into storage.
Shared data needs a named owner. GroupBWT turns the access, quality, lineage, and audit rules into daily operating practices once ownership is assigned.
We start testing from a number in the final report. We trace that number backwards through the load, transformation, mapping, and source.
A correct figure can still be misread. We design the charts and visual layouts that show each team the trend behind it.
For your team, the pipeline output is where report building starts. BI work turns its approved output into shared metrics, dashboards, and scheduled reports.
When can external engineering help an internal team?
Your own team may know the systems well and still lack the hours for a pipeline rebuild. On a defined scope, we add architecture, implementation, and validation capacity, and data ownership stays where it was. GroupBWT engineers can set up repeatable controls while your team keeps the agreed ownership. So who does what? That depends on urgency, in-house capacity, pipeline risk, and long-term support needs.
When is ETL the better fit?
Data like patient records, which must be cleaned or masked before storage, goes through ETL. ELT works when a cloud warehouse has the compute to transform raw history itself after loading. Operating cost and report freshness tip the balance too. Many estates use both, and GroupBWT recommends the split only after checking these conditions against your reports.
How are unexpected updates to external software handled?
Depending on the architecture, GroupBWT can add schema-change detection, quarantine rules, and alerts. These controls flag affected records before downstream processing. Teams may update transformations, review the source contract, or accept a documented change. The mechanism depends on source behavior and the operating model.
How do you protect executive reports during system updates?
The validation plan reflects the project type, infrastructure, and approved reporting baseline. GroupBWT documents the checks, reviewers, and release conditions. Results are reviewed before production release. For platform moves, migration covers detailed cutover and rollback planning.
Is there homework before the first call?
A little. Jot down which systems hold your data: ERP, CRM, product databases, partner feeds. Then add the three to five reports or KPIs people grumble about most. How fresh must each report be? That answer and any compliance limits on where data may be stored or processed are worth writing down. A finished architecture or tool shortlist is not required. The conversation uses this input to define the smallest scope that restores trust in the reports that matter first.
How can we help you?
We’ll review your goals and suggest the right solution — technical, scalable, and tailored to you.
What do you need extracted, structured, or automated?