Machine Learning Development Services
GroupBWT builds forecasts, classifiers, and decision models through our machine learning development services. We prepare the data and test the model before linking its output to your software. The introductory conversation lets you describe the proposed build and us discuss its development scope.

We are trusted by global market leaders


What Our Clients Say

What do you like best?
Their deep understanding of our needs and how to craft a solution that provides more opportunities for managing our data. Their data solution, enhanced with AI features, allows us to easily manage diverse data sources and quickly get actionable insights from data.
What do you dislike?
It took some time to align the a multi-source data scraping platform functionality with our specific workflows. But we quickly adapted and the final result fully met our requirements.

What do you like best?
It was incredible how they could build precisely what we wanted. They were genuine experts in data scraping; project management was also great, and each phase of the project was on time, with quick feedback.
What do you dislike?
We have no comments on the work performed.

What do you like best?
GroupBWT is the preferred choice for competitive intelligence through complex data extraction. Their approach, technical skills, and customization options make them valuable partners. Nevertheless, be prepared to invest time in initial solution development.
What do you dislike?
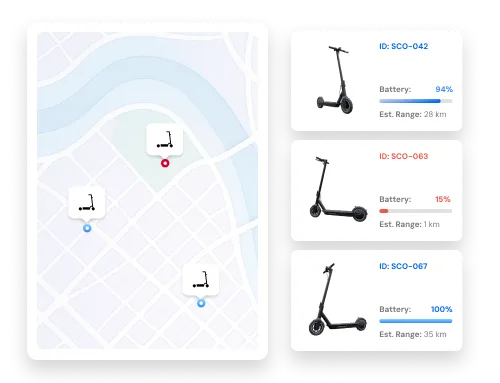
GroupBWT provided us with a solution to collect real-time data on competitor micro-mobility services so we could monitor vehicle availability and locations. This data has given us a clear view of the market in specific areas, allowing us to refine our operational strategy and stay competitive.

What do you like best?
The company's dedication to understanding our needs for collecting competitor data was exemplary. Their methodology for extracting complex data sets was methodical and precise. What impressed me most was their adaptability and collaboration with our team, ensuring the data was relevant and actionable for our market analysis.
What do you dislike?
Finding a downside is challenging, as they consistently met our expectations and provided timely updates. If anything, I would have appreciated an even more detailed roadmap at the project's outset. However, this didn't hamper our overall experience.

What do you like best?
GroupBWT excels at providing tailored data scraping solutions perfectly suited to our specific needs for competitor analysis and market research.
What do you dislike?
Given the complexity and customization of our project, we later decided that we needed a few additional sources after the project had started.
What do you like best?
What we liked most was how GroupBWT created a flexible system that efficiently handles large amounts of data. Their innovative technology and expertise helped us quickly understand market trends and make smarter decisions.
What do you dislike?
The entire process was easy and fast, so there were no downsides.
What do you like best?
Their deep understanding of our needs and how to craft a solution that provides more opportunities for managing our data. Their data solution, enhanced with AI features, allows us to easily manage diverse data sources and quickly get actionable insights from data.
What do you dislike?
It took some time to align the a multi-source data scraping platform functionality with our specific workflows. But we quickly adapted and the final result fully met our requirements.
What do you like best?
It was incredible how they could build precisely what we wanted. They were genuine experts in data scraping; project management was also great, and each phase of the project was on time, with quick feedback.
What do you dislike?
We have no comments on the work performed.
What do you like best?
GroupBWT is the preferred choice for competitive intelligence through complex data extraction. Their approach, technical skills, and customization options make them valuable partners. Nevertheless, be prepared to invest time in initial solution development.
What do you dislike?
GroupBWT provided us with a solution to collect real-time data on competitor micro-mobility services so we could monitor vehicle availability and locations. This data has given us a clear view of the market in specific areas, allowing us to refine our operational strategy and stay competitive.
What do you like best?
The company's dedication to understanding our needs for collecting competitor data was exemplary. Their methodology for extracting complex data sets was methodical and precise. What impressed me most was their adaptability and collaboration with our team, ensuring the data was relevant and actionable for our market analysis.
What do you dislike?
Finding a downside is challenging, as they consistently met our expectations and provided timely updates. If anything, I would have appreciated an even more detailed roadmap at the project's outset. However, this didn't hamper our overall experience.
What do you like best?
GroupBWT excels at providing tailored data scraping solutions perfectly suited to our specific needs for competitor analysis and market research.
What do you dislike?
Given the complexity and customization of our project, we later decided that we needed a few additional sources after the project had started.
What do you like best?
What we liked most was how GroupBWT created a flexible system that efficiently handles large amounts of data. Their innovative technology and expertise helped us quickly understand market trends and make smarter decisions.
What do you dislike?
The entire process was easy and fast, so there were no downsides.

Machine Learning Solutions for Business Operations
Your team’s decision defines the test we agree for the output. We agree those targets for each solution.
Sales and Demand Forecasting
Last month’s sales show what happened; a stock planner also needs a forecast of demand. GroupBWT builds demand forecasts from historical data for stock and budget decisions. We evaluate forecast errors against the planning task before connecting the output to your workflow.
Routine Decision Automation
Staff may spend hours approving similar records. Our models classify incoming requests for routing under the agreed rules. Automated decisions and decisions reserved for a reviewer are defined by your team.
Product and Content Recommendations
Customers can struggle to locate relevant products in a large catalog. Behavior data provides the ranking input for the product or content recommendations. We can evaluate conversion and order value in the deployed experience; model accuracy alone does not demonstrate either improvement.
Visual Inspection and Verification
Images are possible inputs for quality checks, inventory tracking, and document verification. We scope the visual condition to detect and the training images available for it. Staff review flagged images instead of inspecting every image manually.
Document and Text Processing
We extract contract, invoice, or support-log fields into records. The pipeline extracts or classifies those text fields. In the published banking project, GroupBWT built multilingual classification with traceable risk flags. Analysts could inspect the reason a transaction narrative was flagged.
For dedicated text, voice, and document tasks: NLP Services
What We Build and Maintain
From training inputs to the deployed model, our custom machine learning development services cover the build and agreed maintenance.
We establish the prediction or classification with your team and agree its data inputs and success measure. The assessment then checks those records against the task and acceptance target before development starts.
Training records may need formats reconciled or missing fields addressed first. We clean and organize the agreed records to prepare the training inputs. Your team gets a repeatable data preparation flow, replacing spreadsheet fixes made by hand.
The data available limits what the model can learn for the specified task. GroupBWT tailors machine learning development services to the required prediction or classification. We choose the model for the frequency and use of its predictions.
Acceptance needs evidence beyond performance on training records. We use prepared records for training and tuning; the acceptance test uses held-out data against agreed criteria. Your team examines the errors and performance results before approving application integration.
A prediction has to reach the person or system that acts on it. Our machine learning app development services give your existing applications access to model outputs through agreed interfaces. Result delivery and failed-request handling are specified for the application.
We package the model version chosen for release in the selected environment. Deployment includes the application connection and the checks agreed for that release. Your team can identify that deployed version from the release record.
The inputs arriving after release may differ from the training records. The responsible team uses checks on prediction quality, response time, and input changes to investigate declining performance. An alert goes to review before retraining is chosen as the response.
We maintain the model and its application connections within the agreed support scope. Incident investigation and bug fixes can be included, along with infrastructure maintenance and model updates. Coverage and response expectations are defined in the support agreement below.

Discuss Your Machine Learning Use Case
Describe a task you want the model to support. We’ll discuss that task’s data needs and the scope our bespoke machine learning development services could cover.
AI and Machine Learning Services for Your Project
Some projects need readiness work or advice; others need a prototype or broader AI integration alongside development. You may need one of these services, not every stage in the list.
Prepare Reliable Data for Machine Learning
Model development needs reliable inputs. These services address that data work, while the AI implementation route covers the wider rollout.
From Prototype to Deployment
The task, data, and integration scope determine the delivery sequence we agree. The checkpoint requires your team’s decision on proceeding.
Machine Learning Applications Across Industries
Insurance
Claims triage is one possible Insurance use; suspected-fraud detection and policy-risk assessment are others. Reviewers investigate records in priority order.
Finance
Transaction fraud and customer churn are possible prediction targets. Credit and portfolio models require evaluation against the intended decision and the institution’s controls.
Healthcare
Admission forecasts can support resource planning. Structuring medical records or assisting review are other possible uses, subject to the clinical and privacy requirements of the workflow.
Manufacturing
An inspection team can review equipment flagged by predictive-maintenance models. Visual models can flag possible production defects for quality review.
Who Builds and Runs Your Model
01
Machine Learning Solution Architect
Your business objectives determine the model requirements and system architecture that the solution architect defines.
02
Data Engineer
Preparing data pipelines for training and inference, and maintaining those pipelines, is the data engineer’s job.
03
Machine Learning Operations Engineer
Deployment of trained models belongs to the machine learning operations (MLOps) engineer, along with monitoring their live performance.
04
Project Manager
Tasks and timelines sit with the project manager. That person provides your status reports and handles delivery questions.
Protect Your Data and Support the Model
Infrastructure and Application Connections
We review your systems before choosing environments and interfaces. The components listed here are possible choices, not a compulsory stack.
AWS, Microsoft Azure, and Google Cloud are candidate hosts for the selected components. We review the required access and deployment controls before choosing the environment. Your existing infrastructure and the model’s operating needs inform that decision.
Snowflake, PostgreSQL, MongoDB, or BigQuery may supply model inputs through the agreed data interfaces. We review the records available and how the model will read them. We define that connection around the permissions and data format in your system.
A Python service can package the model for deployment, with Docker as a possible container choice. Other applications connect through application programming interfaces (APIs). Orchestration tools are selected only for the requirements of the environment and operating scope.
Customer-management and resource-planning software may need to request predictions or receive model outputs. We review the interfaces available in your applications before defining the connection. The integration scope specifies where the result appears and who uses it.
Project Delivery or Team Extension
Our machine learning software development services can cover a complete build, extend your engineering team, or proceed through separately agreed phases.
Complete Project Delivery
GroupBWT manages the agreed development scope from data preparation through model integration. One provider coordinates the build in this arrangement. The scope defines responsibilities and acceptance criteria.
Internal Engineering Team Extension
Our engineers work alongside your staff to add the required technical capacity. Your team retains responsibility for its wider roadmap. We agree which work our engineers own and how that work is reviewed within your delivery process.
Separately Scoped Project Phases
Each phase sets out the deliverables and the criteria by which they are accepted. Your team approves the next scope after reviewing the phase results. Commitments for later phases remain separate when their scope depends on data readiness or test results.
Our Awards and Partnerships



FAQ
What determines the development budget?
We quote after reviewing data preparation, model requirements, and application connections. The prototype’s quote covers prototype work, not the different production scope. The quote records whether monitoring, infrastructure, and support are part of the price or separately charged options.
What determines the development schedule?
Data access and quality set when training can start. Evaluation can identify where examples or the model approach need improvement. We review integration and deployment requirements alongside those dependencies before agreeing the schedule.
When should we consider custom machine learning?
Ready-made software may cover the task. We recommend custom models for predictions based on operational data or outputs needing a specific software connection. The task and expected value determine our recommendation, rather than the technology label.
How do you arrange overlap with our team?
We agree working-hour overlap with your team during project planning. Delivery updates and the communication tools are included in that arrangement. The agreed overlap needs to accommodate your project’s reviews and decisions.
Can architects attend sessions on-site?
The remote team uses secure cloud tools to work with you. Solution architects can join strategy or kick-off sessions on-site if requested.
Does ownership include third-party components?
Custom ownership does not cover third-party components. Their licenses apply alongside your contract’s ownership terms.

You have an idea?
We handle all the rest.
How can we help you?